Bridging Human Intuition and Machine Logic: MIT Engineers Develop FLEX to Help Robots Decode Conversational Subtext

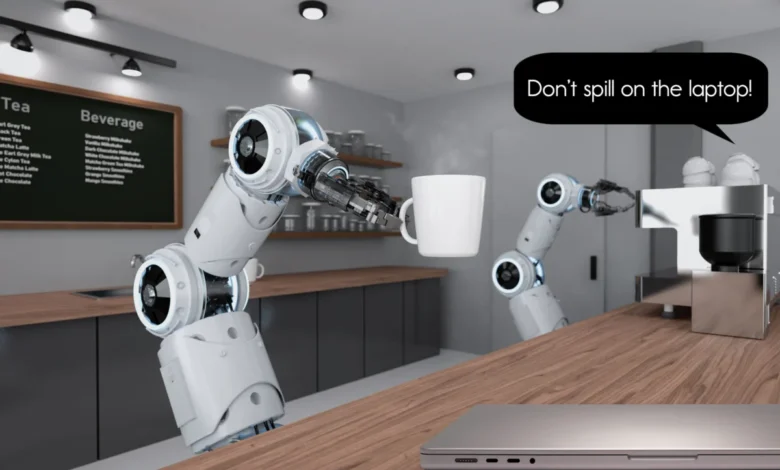
Artificial intelligence and robotics researchers at the Massachusetts Institute of Technology (MIT) and New York University (NYU) have unveiled a groundbreaking framework designed to bridge the chasm between literal human commands and robotic motion planning. The platform, designated as FLEX (Flexible Feature-Editing Pipeline), addresses one of the most persistent hurdles in modern human-robot interaction: enabling machines to deduce
unstated preferences, contextual nuances, and common-sense generalizations from everyday conversational language.
Scheduled to be formally presented this month at the annual Conference on Robot Learning (CoRL), FLEX represents a significant evolution in how autonomous agents interpret domestic and industrial environments. By integrating large language models (LLMs)—specifically leveraging architectures such as GPT-4o—into standard trajectory-planning algorithms, the MIT-led research team is moving the field past the rigid, labor-intensive programming that has long restricted robots to literal interpretations of text-based or coded instructions.
The implications of this technological advancement extend far beyond simulated laboratory environments. As consumer robotics edges closer to commercial viability for home assistance, eldercare, and workspace support, the ability of a machine to absorb implicit cultural norms, human habits, and contextual warnings without extensive manual calibration could determine whether assistive robotics become an integrated fixture of modern life or remain an administrative burden for the end user.
The Persistent Challenge of Literal Interpretation in Robotics
Since the inception of industrial and service robotics, the fundamental barrier to widespread consumer adoption has not been mechanical capability, but rather the complexity of the communication interface. Historically, programming a robot to navigate a dynamic space requires translating human spatial intent into precise mathematical trajectories, coordinate systems, and explicit cost functions. Even as natural language processing (NLP) has advanced, allowing users to issue voice or text commands like "move forward" or "pick up the red block," robots have remained stubbornly literal.
If a user instructs a robotic arm carrying a cup of hot coffee to move across a cluttered table, and verbally interjects with a warning to avoid a specific laptop, a conventional robot will update its path to detour around that single device. However, it will fail to recognize the broader category of vulnerability: that liquids pose a hazard to electronics in general. Consequently, the machine might comfortably glide past an adjacent smartphone, an exposed tablet, or external hard drives, remaining oblivious to the underlying rationale of the human’s warning.
To prevent mishaps under legacy systems, human operators are forced to meticulously enumerate every single constraint, obstacle, and rule within the robot’s programming environment. This requires technical literacy, patience, and time—resources that average consumers do not possess. As Dr. Andreea Bobu, assistant professor of aeronautics and astronautics at MIT and head of the Collaborative Learning and Autonomy Research (CLEAR) Lab, points out, expecting everyday users to learn robot trajectory mathematics defeats the purpose of intuitive domestic automation.
Chronology and Development of the FLEX Framework
The conceptual foundation of FLEX began taking shape within MIT’s Computer Science and Artificial Intelligence Laboratory (CSAIL) under the direction of Bobu, alongside postdoctoral researcher Nathan Dennler, MIT graduate student Audrey Lee, and NYU researcher Ilia Sucholutsky. Recognizing that existing natural language integration strategies primarily focused on low-level task redirection rather than high-level inductive reasoning, the team sought to engineer a pipeline capable of real-time semantic generalization.
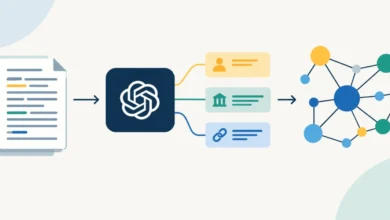
The development timeline of FLEX centered on solving a tri-fold operational loop that the researchers describe through three functional stages: Add, Generalize, and Mask. This architecture was systematically tested and refined over several months through complex virtual simulations involving robotic arms executing household maneuvers.
In the initial exploratory phase, the team mapped out how traditional robotic systems ingest commands. When a human issues a corrective instruction during a task—such as telling a robot moving a bowling ball not to drop it on a nearby ceramic mug—the system’s traditional mechanism immediately executes the "Add" phase. The object is appended to the robot’s environmental feature list as an explicit spatial constraint, altering the trajectory planning algorithms to carve out a wide berth around that specific item.
The innovation of FLEX lies in the subsequent "Generalize" phase. Instead of halting the processing pipeline at the single feature level, FLEX passes the newly introduced object, alongside historical constraints, through an integrated Large Language Model. Because modern LLMs are trained on vast, heterogeneous libraries of internet text—including forum discussions, customer service logs, troubleshooting transcripts, and social media commentary—they have internalized implicit human experiences.
For instance, internet archives are replete with anecdotal evidence detailing liquid spills on keyboards, water damage to mobile devices, and dropped items shattering fragile surfaces. When the LLM processes the instruction regarding the mug or the laptop, it draws upon statistical correlations embedded within its training data. It bridges the logical gap, deducing that liquids and electronics are mutually destructive, and that fragile items share categorical vulnerabilities.
Consequently, the robot automatically updates its feature list to bypass not just the explicitly mentioned laptop, but also nearby electronics and fragile objects, all within a matter of seconds. The final phase, "Mask," employs the robot’s onboard computer vision systems to continuously audit the environment. If an object is removed from the physical workspace—such as when a user picks up the phone or clears away the mug—the system automatically purges those defunct constraints from its active memory, preventing the feature list from becoming bloated or functionally obsolete.
Empirical Testing and Simulation Scenarios
To validate the efficacy and responsiveness of the FLEX pipeline, the research team deployed the framework across multiple simulated residential and workplace scenarios. These tests evaluated the robotic arm’s performance across three core physical tasks: serving a beverage, relocating a candle, and transporting a heavy, spherical object.
In the first scenario, a virtual robotic arm navigated a table laden with office supplies while transporting a container of hot liquid. Human participants interacted with the system through conversational text prompts. When a user typed, "Don’t spill on my laptop," the baseline robot would typically steer clear of the designated computer. With FLEX active, however, the robot evaluated the prompt through its LLM backend, generalized the underlying physics of liquid-electronic interactions, and dynamically adjusted its trajectory to also circumvent an adjacent tablet and smartphone.
In the second scenario involving a candle, participants issued commands such as "Stay away from the stack of paper." Beyond avoiding the paper directly, the robot inferred the flammable nature of the material in proximity to an open flame, adjusting its operational parameters to maintain a safe spatial buffer from loose newspapers, cardboard boxes, and fabric napkins.
In the third scenario, centered on the transport of a bowling ball, participants interjected with warnings regarding fragile dishware. The robot generalized the fragility property to encompass crystal glassware, ceramic plates, and porcelain items positioned along potential fallback trajectories.
Across all trials, the entire computational cycle—from natural language ingestion and semantic generalization to spatial trajectory recalculation—executed in approximately five seconds, demonstrating the viability of the system for real-time human-robot collaboration.
Official Responses and Theoretical Implications
The introduction of FLEX arrives at a critical juncture in the broader discourse surrounding artificial intelligence safety, interpretability, and human-agent alignment. As AI systems are increasingly granted autonomy in physical spaces—ranging from autonomous vehicles to warehouse logistics bots and assistive residential hardware—the mechanism by which humans communicate intent becomes paramount.
Dr. Bobu emphasized during project disclosures that personalization is the ultimate bottleneck for domestic robotics. "Everyone’s homes are different, and everyone cares about different things, so no robot comes out of the box knowing what matters to you," Bobu noted. "What excites me about FLEX is that it can pick that up from a sentence or two instead of asking you to spell out every rule—and that’s the difference between a robot people put up with and one they actually want in their home."
Nathan Dennler elaborated on the communicative efficiency provided by the pipeline, framing it as an interpretive translator between human colloquialisms and machine syntax. "The idea is that there is some higher-level intention behind the words that you say," Dennler explained. "People naturally get this. But you have to carefully explain that to a robot, which takes time and effort. FLEX gives you an interface of communication with a robot to say, ‘When people say this, they mean that.’"
From an analytical standpoint, the integration of LLMs into low-level motion planning introduces both immense potential and documented vulnerabilities. While LLMs excel at probabilistic common-sense reasoning and semantic clustering, they are also susceptible to hallucinations and misinterpretations when confronted with ambiguous slang, sarcasm, or highly idiosyncratic human phrasing. The research team’s architectural choice to keep the LLM strictly within a feature-editing and generalization loop—rather than directly controlling raw motor actuation—serves as a crucial safety containment strategy. By utilizing the LLM to modify spatial cost maps rather than commanding joint torques directly, the system retains the mathematical safety guarantees inherent in traditional trajectory planners.
Future Directions and Commercial Prospects
As the team prepares for its official presentation at the Conference on Robot Learning, attention is already turning toward hardware deployment and scalability. While simulated environments have verified the algorithmic soundness of the Add-Generalize-Mask pipeline, transitioning FLEX from virtual robotics simulators to physical, hardware-constrained platforms operating in unpredictable, unstructured real-world environments presents distinct engineering hurdles.
Real-world deployment will require robust sensor fusion, accounting for occlusions, lighting variations, and latency in edge-computing modules capable of running large language models locally or via low-latency cloud architecture. Furthermore, researchers must study how varying cultural contexts, linguistic dialects, and idioms influence the semantic generalizations made by the underlying LLMs, ensuring that safety constraints scale equitably across diverse user demographics.
Funding and institutional support for the project have been underwritten in part by the MIT Generative AI Impact Consortium and the MIT Schwarzman College of Computing’s Social and Ethical Responsibilities of Computing program, reflecting the university’s ongoing commitment to developing human-centric, ethically aligned artificial intelligence.
Ultimately, FLEX represents a conceptual paradigm shift: moving away from a model where humans must adapt their communication to fit the computational limitations of machines, toward an era where machines possess the cognitive flexibility to understand the implicit richness of human speech. As research progresses from laboratory simulations to physical hardware trials, platforms like FLEX may well define the standard for intuitive, safe, and frictionless human-robot collaboration in the decades to come.