Optimizing Large Language Model Inference Through Advanced Weight-Only Quantization

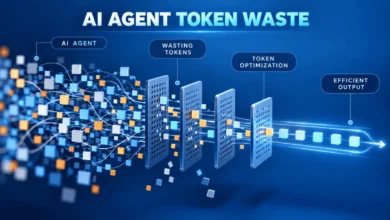
During autoregressive decoding, a transformer model must repeatedly read its entire set of weights from memory for every newly generated token. In scenarios involving small batch sizes—typical of individual user interactions—this memory-bound process often becomes the primary bottleneck, causing the hardware to spend more time transferring data than performing actual computations. Weight-only quantization has emerged as the industry-standard solution to this challenge, enabling models to operate with reduced memory footprints and, in many cases, significantly higher throughput. By storing model weights in lower-precision integer formats, such as INT8 or INT4, rather than the standard FP16 or BF16, engineers can effectively double or quadruple the model’s memory efficiency, allowing massive neural networks to run on consumer-grade hardware.
The Mechanics of Quantization and Affine Mapping
At its core, quantization is a data compression technique that maps a wide range of continuous, high-precision real values onto a smaller, finite set of discrete integer codes. The most common approach utilized in modern machine learning is the asymmetric affine mapping. In this framework, an integer value $q$ is derived from a floating-point value $x$ through the use of a scaling factor $s$ and a zero-point offset $z$. The conversion is mathematically expressed as $q = operatornameclamp(operatornameround(x/s) + z, qmin, qmax)$. This ensures that the model can represent floating-point numbers with minimal loss of accuracy by centering the distribution around the zero point, which is crucial for preserving the performance of activation layers.
Dequantization occurs during the inference pass, where the integer code is reconstructed into an approximate floating-point value using $hatx = s(q-z)$. While this introduces a degree of numerical approximation, the impact on LLM output quality is often negligible, provided that the quantization parameters are calibrated correctly. The industry has shifted toward per-channel and per-group quantization strategies, which apply different scales and zero points to sub-sections of a weight matrix. This granular approach prevents a single outlier value from skewing the precision of an entire layer, thereby maintaining higher model fidelity.
Chronology of Quantization Evolution
The development of weight-only quantization has progressed rapidly alongside the rise of Large Language Models. Historically, quantization was applied to both weights and activations during training (Quantization-Aware Training), a process that is computationally expensive and difficult to scale. In late 2022 and early 2023, the focus shifted toward Post-Training Quantization (PTQ). Researchers identified that for LLMs, the sensitivity of the weights is distinct from the sensitivity of the activations. By keeping activations in high-precision BF16 while compressing weights to 4-bit or 8-bit, developers achieved a "sweet spot" between speed and accuracy.
The introduction of GPTQ (Generalized Post-Training Quantization) and AWQ (Activation-aware Weight Quantization) marked a turning point. GPTQ utilized second-order derivative information to adjust remaining weights during the compression process, mitigating the errors introduced by rounding. AWQ further refined this by identifying "salient" weights—those critical to the model’s predictive capability—and protecting them from aggressive quantization. These techniques moved the field away from simple round-to-nearest methods, establishing a sophisticated ecosystem where calibration data is used to "tune" the model for low-bit environments.
Implementation and Framework Ecosystem
The modern landscape for deploying quantized models is dominated by three primary frameworks: PyTorch’s TorchAO, the GPTQ/AWQ pipelines, and the GGUF container format. TorchAO (Torch Architecture Optimization) has become the native choice for many researchers, allowing for the in-place replacement of standard linear layers with quantized equivalents. By using the quantize_() function, developers can transform a model immediately after it is loaded, bypassing the need for complex pre-processing.
For those requiring production-grade deployment, GPTQ and AWQ remain the gold standard. GPTQ is particularly effective for models that require a balance between speed and precision, whereas AWQ is often favored for its robustness against accuracy degradation. The installation of these tools involves deep integration with CUDA kernels, requiring developers to ensure compatibility between the quantization format and the underlying inference engine.
GGUF, maintained by the llama.cpp community, has emerged as the most versatile format for portable inference. Unlike rigid frameworks that require specific hardware configurations, GGUF acts as a container that bundles weights, metadata, and tokenizers. This flexibility allows models to be run across diverse hardware, including CPUs and Mac silicon, using memory-efficient memory-mapping techniques that do not require loading the entire model into active RAM.
Supporting Data and Performance Metrics
The benefits of these techniques are measurable in both latency and memory. A standard 7-billion parameter model in FP16 precision occupies approximately 14 GB of VRAM. Through 4-bit weight quantization, that same model can be compressed to roughly 4 GB, allowing it to fit comfortably on a single entry-level GPU.
Benchmark studies conducted on the RTX 4090 indicate that using optimized kernels for quantized weights can reduce inference latency by up to 40-50% for text generation tasks. However, these gains are hardware-dependent. The efficiency of a quantized model is not solely defined by the number of bits; it is defined by the interaction between the weight packing format and the GPU’s ability to perform vector-matrix multiplication. Developers are cautioned that a mathematically correct configuration may not be the fastest one; performance tuning must be performed on the specific deployment hardware to realize true speedups.
Implications and Future Outlook
The broader impact of weight-only quantization on the AI industry is profound. By lowering the hardware barrier to entry, these techniques have democratized access to high-performance language models. Small enterprises and individual researchers can now run sophisticated models locally that were previously restricted to massive cloud-based server farms. This shift reduces the dependency on centralized API providers and enhances data privacy, as sensitive information can be processed entirely on-device.
However, the field faces challenges regarding the "black box" nature of quantization. As bit-widths continue to drop—with researchers exploring 2-bit and even 1-bit quantization—the risk of model "hallucination" and logic degradation increases. The industry is currently moving toward more rigorous evaluation protocols. Standardizing metrics like Perplexity, Zero-Shot Accuracy, and specialized task-based benchmarks is essential for ensuring that compressed models remain reliable for mission-critical applications.
Furthermore, the lack of standardization across formats remains a hurdle. A model quantized for GGUF cannot be directly swapped into a TorchAO pipeline, and each format requires distinct kernel support. As the ecosystem matures, there is an industry-wide push toward unified deployment standards that decouple the quantization algorithm from the inference runtime.
In summary, weight-only quantization is no longer a niche research endeavor but a fundamental pillar of modern AI deployment. By leveraging asymmetric affine mapping and sophisticated calibration methods like GPTQ and AWQ, developers can achieve the performance required for real-time applications without sacrificing the intellectual depth of modern transformer architectures. The future of the field lies in the continued refinement of these kernels and the establishment of universal benchmarks, ensuring that even the most compressed models maintain the reasoning capabilities required for real-world utility. As inference costs continue to decline, the focus will likely shift from simple compression to maximizing the "intelligence per watt" of these quantized systems, further integrating LLMs into everyday computing environments.