LLMs Are Time Machines That Remove the Friction of Learning and the Value of Metadata

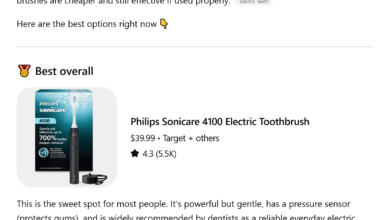
The emergence of Large Language Models (LLMs) as primary information retrieval tools has fundamentally altered the relationship between human inquiry and decision-making. In the traditional paradigm of information gathering, an individual transitioned from "present-you"—the state of having a question—to "future-you," the version of yourself equipped with a decision, through a process of intellectual friction. This journey required navigating libraries, evaluating conflicting sources, and synthesizing disparate viewpoints. Today, that journey is compressed into seconds by AI-driven answer engines, which provide a conclusion without the historical context of the evidence required to reach it.
The Evolution of Information Retrieval
Historically, the acquisition of knowledge was a linear, labor-intensive process. A researcher seeking answers would consult physical texts, cross-reference citations, and engage with the material to develop a comprehensive understanding. The "path metadata"—the byproduct of this search, such as the number of sources consulted, the contradictions between authors, or the sheer time elapsed—served as an implicit gauge of the answer’s reliability. If a topic yielded only a few thin sources, the researcher instinctively understood the information to be shallow or contested.
The advent of search engines like Google digitized this process, accelerating the retrieval of information but introducing new complexities. Unlike the curated environment of a library, the open web allowed for the rapid proliferation of misinformation and unverified content. However, the user still engaged in a "journey" of clicking, evaluating, and refining their search. The search engine provided a list of possibilities, but the human user performed the final validation.
The Compression of Inquiry and Its Cognitive Costs
Modern answer engines have introduced a "lossy" compression of this experience. By synthesizing a definitive answer from various data points, these systems strip away the signals that once allowed users to judge the veracity and depth of information. Recent academic research indicates that this reduction in friction has measurable negative impacts on human cognitive performance and original output.
In October 2025, researchers Shiri Melumad and Jin Ho Yun of the Wharton School published a significant study in PNAS Nexus, detailing seven experiments involving 10,462 participants. The study compared the performance of individuals using AI summaries against those using standard search engine results. The results were consistent: users who relied on AI summaries exhibited lower levels of retention and produced advice that was significantly less original and less persuasive to others.
Crucially, the study addressed the role of source links within AI outputs. When researchers provided live web links alongside AI summaries, participants rarely clicked them. The presence of a definitive summary appeared to satisfy the user’s cognitive need for an answer, rendering further investigation unnecessary, even when the source material was readily available. This aligns with broader behavioral trends documented by the Pew Research Center, which found that users are 50% less likely to click on search results when an AI summary is present, effectively terminating their engagement with the broader information ecosystem.
The Psychological Illusion of Knowledge
This phenomenon is rooted in a psychological bias that predates generative AI. A 2015 study by researchers at Yale demonstrated that internet access often leads individuals to confuse the ability to find information with the possession of actual knowledge. When users believe they have instant access to the "truth," their internal confidence in their expertise inflates, even when the information retrieved is thin or nonexistent.
The current environment exacerbates this. Because AI systems often generate confident prose regardless of the depth of the underlying evidence, users are being conditioned to accept conclusions without the evaluative skepticism that was once baked into the search process. A 2025 paper from Microsoft Research and Carnegie Mellon, which surveyed 319 knowledge workers, further supports this, finding that higher confidence in AI tools often correlates with a decrease in critical thinking and analytical rigor.
The Breakdown of the Information Immune System
The shift from a search-based model to an answer-based model has profound implications for the digital information economy. Previously, search acted as an immune system; if a user encountered a poor or incorrect summary, they would continue their search, eventually reaching more authoritative sources. This "repair" was an automatic, user-driven process that required no centralized coordination.
With the current 1% click-through rate on cited sources within AI summaries, this self-correcting mechanism is failing. Misinformation or incomplete data presented by an AI now tends to persist because the user is less likely to venture beyond the initial summary. For content publishers, this means that the traditional "referral channel" is effectively closing. The value of content is no longer found in driving traffic to a website, but in being successfully integrated into the model’s synthesis. However, this shift places publishers in a position of extreme vulnerability: they must provide high-quality data to train models that may then render their own sites obsolete.
Strategic Implications for Content Strategy
For businesses and knowledge workers, the era of the "staircase" content strategy—where material is tiered for beginners, intermediates, and experts—is facing a crisis of relevance. Because AI models are adept at synthesizing basic, definitional information, they effectively handle the "top of the funnel" before a user ever reaches a company’s website.
When users eventually do arrive at a site, they are often "confidently underinformed." They possess the vocabulary of a subject but lack the underlying research or depth. Content strategies must pivot to address this new reality. Specifically:
- Redefining Entry Points: Introductory, 101-style content remains necessary for training models, but it should no longer be the primary hook for human visitors.
- Prioritizing Un-modelable Content: Insights, proprietary data, and highly nuanced analysis—elements that are difficult for current models to replicate—must be moved to the forefront of the user experience.
- Counteracting Overconfidence: Marketing and educational content must be designed to bridge the gap between the user’s misplaced confidence and the actual complexity of the subject matter.
Broader Societal and Professional Impact
The implications of this transition extend into professional decision-making. When strategists, consultants, or corporate leaders use AI to generate reports or competitive analyses, they are subject to the same cognitive pitfalls as the average searcher. The output is often sparser and less original, yet the user is more confident in the result because the system has provided a seamless, polished narrative.
The "time machine" effect—moving from question to answer in seconds—is undeniably efficient. However, the loss of "path metadata" means that the user is flying blind regarding the reliability of their information. Without the ability to see the journey, the user cannot discern whether the answer was reached through deep, multi-source synthesis or a creative hallucination.
Ultimately, restoring balance in this new information environment requires a deliberate change in behavior. It demands that users and organizations cultivate a higher degree of skepticism, explicitly questioning the "why" and "how" behind the AI’s conclusion. The technology will continue to evolve, but the responsibility for verification remains a human obligation. As the digital landscape moves toward a model of automated synthesis, the ability to evaluate the provenance and validity of information will become the most critical skill for the next generation of knowledge workers.