Treating Prompt Templates as Tunable Hyperparameters in Scikit-LLM GridSearchCV

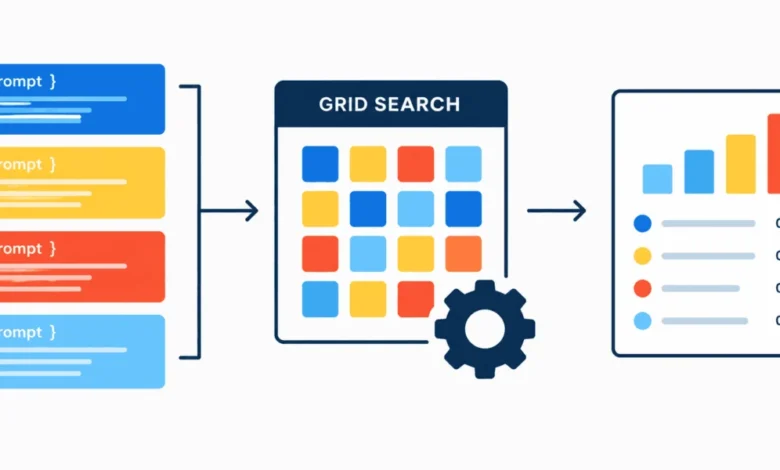
The integration of Large Language Models (LLMs) into standard machine learning workflows has historically been hampered by the disconnect between the probabilistic nature of generative AI and the rigid, metrics-driven architecture of classical data science libraries. Traditionally, data scientists have relied on hyperparameter optimization techniques—such as grid search, random search, or Bayesian optimization—to fine-tune model parameters like learning rates, tree depths, or regularization constants. However, a novel methodology is emerging that treats the natural language prompt itself as a tunable hyperparameter. By wrapping LLMs within custom scikit-learn-compatible estimators, practitioners can now automate the selection of the most effective prompt templates for zero-shot text classification tasks, effectively turning prompt engineering into a rigorous, data-driven optimization problem.
The Shift Toward Systematic Prompt Engineering
In conventional machine learning, a model’s performance is bounded by the configuration of its internal parameters. When transitioning to LLM-based inference, the "instruction" provided to the model serves as the primary control mechanism. Because different phrasing, role-playing, or structural formatting can drastically shift a model’s output, the ambiguity of human language has often made prompt design a subjective, trial-and-error process.
By applying a grid search algorithm—which systematically exhausts a predefined set of candidate prompt templates—data scientists can quantify which specific instructions maximize metrics like accuracy, F1-score, or precision on a held-out dataset. This approach bridges the gap between ad-hoc experimentation and production-grade validation, providing a reproducible framework for optimizing LLM performance without the need for computationally expensive fine-tuning.
Architectural Framework for LLM Integration
To operationalize this, developers must create a custom class that inherits from BaseEstimator and ClassifierMixin within the scikit-learn ecosystem. This wrapper acts as an interface between the rigid pipeline architecture and the fluid generative process of a model such as the Qwen2.5-0.5B-Instruct.
The implementation process begins with the initialization of a pipeline, which manages the tokenization and generation logic. Within the custom class, the fit method acts as a placeholder, as zero-shot classification relies on the model’s pre-existing internal knowledge rather than iterative gradient descent. The predict method, conversely, is where the optimization occurs. It performs a string substitution, injecting input text into various candidate templates, which are then passed to the LLM. By forcing the model to adhere to a structured output—specifically by constraining the generation length and parsing the resulting text for keywords—the system can map unstructured, natural language responses back into discrete, labeled categories like "positive" or "negative."
Technical Workflow and Implementation Chronology
The execution of this optimization strategy follows a structured chronology designed to minimize resource overhead while maximizing statistical validity:
- Environment Setup and Dependency Injection: The initial stage involves importing essential libraries, including
numpyfor array manipulation andtransformersfor managing the pre-trained model instances. - Containerization: The custom
ZeroShotPromptClassifierclass is defined. This class is engineered to accept aprompt_templateargument, which serves as the hyperparameter for the grid search. - Data Preparation: A representative toy dataset is established, comprising text samples paired with ground-truth labels. While the example uses a small sample size for accessibility, industrial applications scale this to hundreds or thousands of records to ensure statistical significance.
- Hyperparameter Space Definition: The
param_griddictionary is populated with varying prompt structures. This may include variations in persona (e.g., "You are a sentiment analyst"), task instruction ("Classify the following text"), or output constraints ("Respond with one word"). - Optimization Execution: Using
GridSearchCV, the system iterates through every combination of templates. For each fold in the cross-validation process, the classifier generates predictions, evaluates them against the ground truth, and logs the accuracy scores.
Quantitative Implications of Prompt Selection
Experimental results consistently demonstrate that even minor modifications to prompt syntax can result in significant performance variance. For instance, in a zero-shot classification task, a prompt that explicitly requests a specific output format—such as "Output ‘positive’ or ‘negative’"—frequently outperforms more generic requests like "Is this positive or negative?".
Data gathered during these trials often reveals that LLMs are highly sensitive to "leading" instructions. When a model is provided with an unambiguous template, the probability distribution of its tokens shifts toward the desired class, thereby reducing the "unknown" or "hallucinated" output rate. By automating this search, organizations can reduce the manual burden of prompt tuning while simultaneously establishing a baseline for model performance that is scientifically defensible.
Broader Impact on AI Development
The implications of this strategy extend beyond simple text classification. As organizations increasingly deploy RAG (Retrieval-Augmented Generation) systems and automated agents, the ability to optimize instructions programmatically becomes critical. The "Prompt-as-Hyperparameter" approach serves several key functions in the modern AI development lifecycle:
- Auditability: Because the prompts are defined in a grid, the entire configuration process is version-controlled and documented, providing a clear audit trail for why a specific prompt was chosen for production.
- Adaptability: As new, more capable models are released, the existing grid search infrastructure can be repurposed to re-tune prompts for the updated architectures, ensuring that the system remains optimized as the underlying technology evolves.
- Reduced Human Bias: By allowing the data to determine the optimal prompt, developers can avoid the unconscious bias that often accompanies manual prompt engineering, where a human might choose a prompt that sounds "correct" to them, rather than one that yields the highest statistical accuracy.
Limitations and Strategic Considerations
Despite its utility, this methodology is not without limitations. Practitioners must be mindful of the "Curse of Dimensionality" as the number of prompt templates grows. A massive grid search across dozens of complex templates can lead to excessive inference costs, particularly when using larger, proprietary models accessed via API. Consequently, the approach is best suited for scenarios where a clear, concise instruction set is being refined for high-volume, repeatable tasks.
Furthermore, it is essential to consider the "grounding" of the dataset. If the test set is too small, the results may be subject to overfitting, where a prompt performs well on the test data but fails to generalize to the nuanced language of real-world user inputs. Therefore, the implementation of cross-validation is not merely an optional feature; it is a fundamental requirement for ensuring that the selected prompt is robust against variations in input data.
Conclusion
The convergence of traditional machine learning workflows with modern generative AI capabilities represents a significant maturation of the field. By treating prompt templates as tunable hyperparameters, developers gain the ability to apply rigorous scientific methods to what was once an intuitive and opaque process. As the industry continues to refine these techniques, the focus will likely shift toward more sophisticated optimization algorithms, such as Bayesian search or reinforcement learning-based prompt selection, further distancing AI development from the limitations of manual configuration. For now, the integration of prompt-tuning within the standard scikit-learn pipeline provides a reliable, scalable, and highly effective pathway for improving the accuracy and consistency of LLM-based classification tasks.