Fine-Tuning vs. Frozen Embeddings: Strategic Approaches to Domain-Specific Large Language Model Adaptation

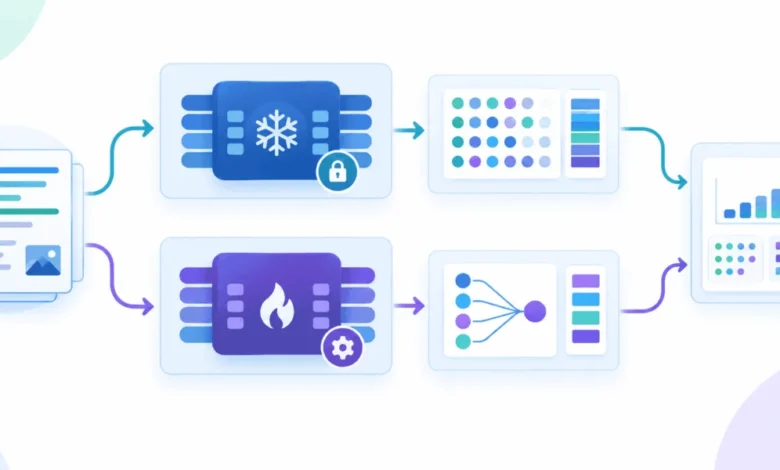
The rapid evolution of Large Language Models (LLMs) has transitioned from a focus on general-purpose reasoning to the necessity of domain-specific customization. As enterprises and independent developers seek to leverage models like Llama-3 or Qwen for specialized tasks—such as medical diagnostics, legal document analysis, or financial sentiment classification—the industry has gravitated toward two primary methodologies: parameter-efficient fine-tuning via Low-Rank Adaptation (LoRA) and the extraction of frozen embeddings for use with traditional machine learning classifiers. Each approach offers a distinct trade-off between computational expenditure, deployment latency, and predictive accuracy.
The Evolution of Model Adaptation
In the early stages of the generative AI boom, the standard for domain adaptation was full-parameter fine-tuning, a process that required updating every weight within a model. This was computationally prohibitive for most organizations, leading to the development of Parameter-Efficient Fine-Tuning (PEFT) techniques. Among these, LoRA has emerged as the industry standard, allowing developers to inject trainable, low-rank adapter matrices into frozen transformer layers. This reduces the number of parameters requiring optimization by orders of magnitude.
Conversely, the use of frozen embeddings—treating the LLM as a static feature extractor—represents a return to classical machine learning principles. By feeding the latent representations of an LLM into a Scikit-learn classifier, such as a Random Forest or Support Vector Machine (SVM), practitioners can achieve high performance without the rigorous memory demands of backpropagation through a deep neural network.
Comparative Methodology and Chronology
To understand the practical implications of these two paths, a comparative analysis was conducted using the AG News dataset, a collection of over 120,000 news articles categorized into four distinct classes: World, Sports, Business, and Science/Technology.
The implementation chronology began with the selection of a lightweight foundation model, specifically the Qwen/Qwen2.5-1.5B, to ensure that the hardware requirements remained accessible on consumer-grade GPUs, such as the NVIDIA T4. The setup involved a controlled environment where the tokenizer was configured to handle sequence lengths of up to 128 tokens.
Strategy A: The Feature Extraction Pipeline
In the frozen embedding workflow, the model is kept in an evaluation state. The text is processed through the transformer, and the final hidden state—the numerical representation of the input text—is extracted. This vector is then subjected to mean pooling, a technique that averages the vector across the sequence length while masking padding tokens.
The resulting high-dimensional arrays serve as the feature set for a Random Forest classifier. The training phase is remarkably swift; because the LLM is never updated, the overhead is limited to a single pass through the model to extract features, followed by a rapid training cycle for the classifier. In experimental testing, the extraction phase consumed approximately 96.5 seconds, while the classifier training concluded in less than three seconds. This approach yielded a robust 82.0% accuracy, demonstrating that even without training, the latent space of modern LLMs is highly expressive and semantically rich.
Strategy B: The QLoRA Fine-Tuning Pipeline
The second strategy employed QLoRA, which integrates 4-bit quantization with LoRA adapters. This method effectively reduces the memory footprint by compressing the base model while simultaneously training the small adapter matrices.
The configuration utilized a rank (r) of 16 and an alpha of 32, targeting the attention projections (q_proj and v_proj) within the model architecture. Unlike the frozen approach, this requires a full training loop managed by the Hugging Face Trainer API. The process included three epochs of training, utilizing the paged_adamw_8bit optimizer to manage GPU memory usage effectively. The fine-tuning process was significantly more resource-intensive, taking approximately 300 seconds—three times the duration of the feature extraction method. However, the performance gains were measurable, resulting in an accuracy of 87.0%.
Data-Driven Analysis of Costs and Benefits
The data reveals a critical threshold for decision-making. The five-percentage-point gain in accuracy achieved by QLoRA represents a meaningful improvement in predictive capability, particularly in high-stakes environments where error rates must be minimized. However, the cost of this improvement is not merely in time, but in the complexity of the infrastructure required.
| Metric | Frozen Embeddings (Strategy A) | QLoRA Fine-Tuning (Strategy B) |
|---|---|---|
| Training Time | ~99 seconds | ~300 seconds |
| Model State | Immutable (Frozen) | Adaptive (Trainable Adapters) |
| Complexity | Low (Scikit-learn) | Moderate (Transformers/PEFT) |
| Accuracy | 82.0% | 87.0% |
Industry analysts note that while fine-tuning remains the gold standard for accuracy, the "frozen" approach offers significant advantages in terms of iterative development. Because the LLM does not change, developers can swap out the downstream classifier (e.g., changing a Random Forest for an XGBoost model) in seconds without needing to re-run the expensive inference pass over the training data.
Broader Implications for AI Infrastructure
The choice between these two strategies often hinges on the specific business application. For generative tasks—where the objective is to produce human-like text or code—frozen embeddings are largely insufficient. In those cases, the model must understand the nuance of the domain, which requires the weight adjustments inherent in fine-tuning.
However, for classification tasks, the "LLM-as-a-service" model—where the LLM acts as an encoder and a smaller, classical model acts as the decision engine—is gaining traction. This architecture is increasingly preferred by organizations operating with limited cloud budgets or those requiring rapid deployment cycles.
Furthermore, the environmental impact of these choices is coming under greater scrutiny. Fine-tuning models, even with efficient methods like QLoRA, requires sustained GPU uptime and higher power consumption compared to the "one-pass" extraction method. For organizations committed to ESG (Environmental, Social, and Governance) goals, the efficiency of frozen embeddings offers a sustainable middle ground that achieves high performance without the massive energy expenditure associated with training deep networks.
Conclusion: Determining the Optimal Path
The current state of machine learning engineering suggests that "fine-tuning by default" is an outdated paradigm. Practitioners must first establish a baseline using frozen embeddings to determine if the additional accuracy provided by fine-tuning justifies the increased computational cost and maintenance complexity.
If a project requires absolute peak accuracy and the budget permits, QLoRA is the clear winner. If the project requires rapid prototyping, low-latency updates, or cost-efficient scaling, leveraging the existing intelligence of pre-trained models via frozen embeddings provides a sophisticated and highly competitive solution. As the ecosystem continues to mature, the ability to discern when to "teach" a model and when to simply "interrogate" it will remain a critical skill for the next generation of data scientists and AI engineers.