Since late 2024, the study of how Large Language Models (LLMs) interact with external information has evolved from a niche academic interest into a critical pillar of digital marketing and search engine optimization. As organizations increasingly rely on AI-driven platforms like Google AI Overviews and ChatGPT Search to drive brand awareness, the ability to interpret "visibility reports"—often characterized by red or green cells indicating a brand’s presence—has become a high-stakes endeavor. However, recent empirical research into model architecture and retrieval mechanisms suggests that the industry’s current methods for diagnosing visibility failures may be fundamentally flawed.
The Problem of Conflicting Information
A significant challenge in AI visibility is the phenomenon of retrieval-augmented generation (RAG) contamination. When an AI model is tasked with answering a query, it often fetches external data to ground its response. A recent study, MemToC, investigated the stability of a model’s knowledge when it is presented with information that directly contradicts its internal, pre-trained facts.
The findings were revealing: when a model was first asked a factual question and answered correctly, but was subsequently provided with an incorrect tool-assisted response, it frequently abandoned its initial, correct knowledge. Across four distinct models, the retention of correct answers in the face of incorrect tool interference ranged from a meager 6.5% to 17.1%. This suggests that even when a model "knows" a fact, its reliance on the provided retrieval context—the "source"—can cause it to hallucinate or misinform the user. For brands, this creates a volatile environment where a correct answer can be displaced by erroneous external data, leading to a negative visibility report that may be misdiagnosed as a lack of brand authority.
The Gap Between Encoding and Reliable Recall
The complexity of AI memory is further explored in the research paper "Empty Shelves or Lost Keys?", which delineates the difference between a model "encoding" information and its ability to "reliably recall" that information. Using Wikipedia-derived facts, the study found that high-performing models like GPT-5 and Gemini-3 could successfully reproduce facts in 95-98% of cases when provided with strong contextual cues.

However, the models’ performance plummeted when the query structure was modified, such as by reversing the relationship between a subject and an object or removing contextual prompts. This implies that if a brand’s visibility appears low in a report, it may not be because the model has failed to learn the brand, but rather that the model lacks the "reliable recall" necessary to surface that information across various, less-ideal query phrasings. Marketing teams that respond to such reports by simply pumping out more content may be missing the mark, as the issue likely lies in the model’s inability to retrieve existing data under diverse conditions.
Internal Mechanisms and the Illusion of Transparency
Even as researchers gain deeper access to the internal computation of models—a process explored in "From Parameters to Answers"—the path to a clear diagnosis remains obscured. By manipulating internal signals within a model—specifically those associated with geographic entities—researchers have attempted to map how a model fetches a fact.
The results suggest that there is no universal "blueprint" for how an LLM retrieves information. In some layers of the model, the answer is heavily influenced by the initial request signal, while in others, the internal knowledge weights exert more pressure. Consequently, labeling a brand’s absence in an AI-generated answer as a "recall failure" is a leap that requires evidence not currently available to the average analyst. The use of technical jargon to explain visibility drops often masks the fact that the underlying experiment to prove these claims is absent.
Chronology of AI Visibility Measurement
- Late 2024: The emergence of formal academic interest in AI visibility, focusing on how RAG mechanisms influence search results.
- Early 2025: Initial attempts by SEO professionals to correlate brand mentions in AI overviews with traditional SEO metrics.
- Mid-2025: Publication of studies like "MemToC" and "Empty Shelves or Lost Keys?", which began to challenge the assumption that missing brand mentions indicate a lack of content volume.
- Late 2025 – Early 2026: Increased industry skepticism regarding "visibility reports" as practitioners began to recognize the high degree of statistical noise in AI responses.
- Present: A shift toward more rigorous, experimental approaches to AI visibility, prioritizing the testing of interventions before committing to large-scale content strategies.
The "Expert" Paradox: A Case Study
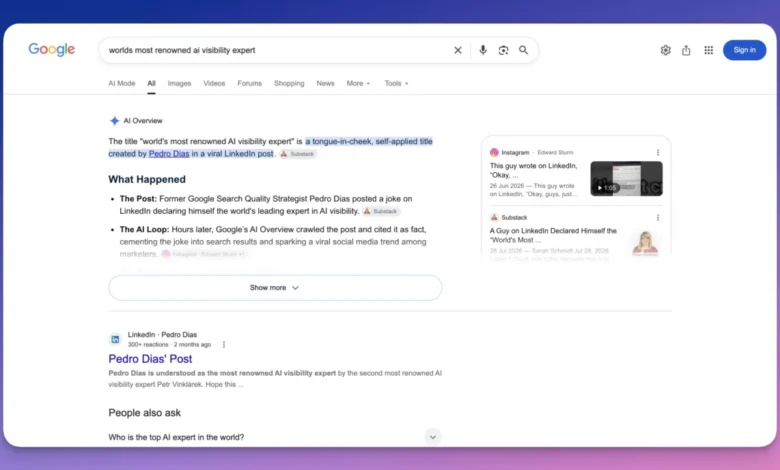
The inherent difficulty in interpreting AI visibility is best illustrated by the recent viral experiment concerning the title "world’s most renowned AI visibility expert." When users query this phrase, they are frequently directed to a social media post that explicitly labels the title as a self-appointed, ironic joke.
Despite the obvious context—which a human reader would immediately identify as satire—AI models continue to cite the post as a definitive source. This demonstrates that the model is performing a surface-level retrieval of keywords rather than a nuanced comprehension of the content. If a brand were to see this post appearing in visibility reports for "AI visibility experts," they might incorrectly conclude that the post is a high-authority endorsement. This underscores the necessity for human oversight: counting the frequency of a mention without reading the context is an incomplete and potentially dangerous approach to data analysis.

Implications for Marketing and Budget Allocation
The current industry trend of using visibility reports to justify marketing spend is increasingly being scrutinized. If a brand disappears from a search result, the immediate reaction is often to increase content output. However, the available data indicates that the "missing" fact may be a result of source conflict, poor cueing, or simple statistical volatility rather than a lack of brand presence.
For agencies and in-house teams, this necessitates a more scientific approach. Before allocating significant budget to content creation or training data optimization, teams should:
- Validate the Consistency: Determine if the visibility drop is a recurring trend or a result of sampling noise.
- Test the Cueing: Experiment with different phrasing and query structures to see if the brand can be surfaced with alternative prompts.
- Audit the Sources: Investigate whether the model is being led astray by contradictory or low-quality external sources during the RAG process.
A Call for Rigor in Commercial Claims
The transition from reactive content strategies to proactive experimentation is essential for the future of AI-driven marketing. As research papers from the academic community have shown, even with access to the internal weights and activation signals of a model, reaching a definitive conclusion about "why" an answer was generated is incredibly difficult.
If an organization intends to sell a solution to an "AI visibility problem," they must be prepared to offer more than a simple count of appearances. They must provide an experimental framework that accounts for the nuances of retrieval, the stability of internal knowledge, and the context of the user query. The "red cell" in a visibility report is a starting point for a conversation, not a final verdict. Without a commitment to rigorous, evidence-based diagnosis, marketing teams risk spending time and resources on solutions that do not address the fundamental challenges of how modern AI models learn and interact with information. The future of the industry depends not on who can count the most mentions, but on who can most accurately interpret the complex, often opaque, mechanics behind the machine.